Application Overview
Upon first login to Snowflake you can find your apps under the Data Products / Apps menu. Then click on the "mpmX" app to open it.

All Scenarios Page
The Snowflake Process Mining App starts with the All Scenarios page. Here you can view all the available process mining scenarios, create new process scenarios or edit and delete existing ones. Each scenario contains all the necessary details for mining your data, including data source definitions within Snowflake and the process mining parameters. You can review and edit existing scenarios, delete them, or add new ones as needed.
The "✎" button takes you to the Data Source page, where you can start editing an existing Process Scenario.
The "⏿" button takes you to the Data Source page, where you can view the Process Scenario configuration. You cannot make any changes to the Process Scenario in this mode.
The "🗑️" button allows you to delete an existing Process Scenario. You must confirm your intention.

Create a Process Scenario
The "➕ Create a Process Scenario" button takes you to a new page.


Here you enter the Process scenario short name and Process scenario description of the new Process Scenario.
You can also decide whether you want to create an OCPM Process Scenario and whether you want to Enable Time Travel.
The scenario name becomes a database schema name, so it must be 1–20 characters, start with a letter, and contain only letters, digits, spaces, hyphens, and underscores (German äöüÄÖÜß are allowed). It must also not resolve to a reserved SQL keyword — for example Order, Select, User, Table, Session, or Current Date. Combined names are fine (User Order becomes the schema USER_ORDER).
Otherwise you'll see: "The name of the process scenario would result in a reserved SQL keyword (like ORDER or SELECT) and cannot be used." Scenarios can't be renamed later, so pick another name (for example Order → Orders). See the full list of reserved keywords in Snowflake.
Import a Process Scenario (JSON)
You can import a scenario from a JSON configuration document from the All Scenarios page.
The Import Process Scenario button is only shown for users who are allowed to create scenarios.
During import, the app validates:
- JSON syntax (for example: unexpected character, line and column)
- Scenario configuration schema (required fields, field types, and allowed values)
Validation errors are shown in a user-friendly format with a clear field location and message, for example:
dataSources → eventLog: is required.name: must not be empty.Unexpected character ... (line 12, column 5)
For SQL-based automation (onboarding and mining from tasks or scripts), see External SQL API. The JSON shape for scenario import is documented under Process scenario configuration (JSON Schema v1).
Export a Process Scenario (JSON)
You can export a scenario as JSON from the scenario sidebar after the scenario has been initialized.
Export is only available for users with scenario management permission (scenario admin / CAN_MANAGE equivalent in your deployment model). Export is read-only and therefore also available when the scenario is opened in view mode.
Data Sources Page
Data sources are the starting point for process mining.
Each data source must adhere to a defined data structure, and our validation process ensures that everything is formatted correctly before moving forward. If you encounter any validation issues while configuring the data sources, see Troubleshooting Data Sources Validation for help.

Select an Event Log
An event log is the central and mandatory input for process mining. It is a table that contains case and event information. To further enrich the event log with your domain specific data, you can also add additional Case and Event Dimensions.
The "➕ Select Table as Event Log" button allows you to reference a table that you can access as an event log. You can change the type of event log before selecting a reference. The dropdown options are Table or View. Apache Iceberg Tables are supported through the Tables option.
Click the "🗑️" button to remove an existing reference which then allows the selection of a different Event Log.

Activity Descriptions
Activity descriptions are optional and let you enrich activity types with readable labels.
Configure activity descriptions alongside your other table references (before Case and Event Dimensions). Use the "➕ Select Table as Activity Descriptions" button. You can change whether the reference is a Table or View before selecting it. The dropdown options are Table or View. Apache Iceberg Tables are supported through the Tables option.
Click the "🗑️" button to remove an existing reference which then allows the selection of a different Activity Descriptions table or view.
As with Case Dimensions and Event Dimensions, you can select this reference only after the scenario has been initialized.
- The selected object must provide:
KEY_ACTIVITY_TYPEAD_ACTIVITY_DESCRIPTION
- During mining, the app joins these values into
ACTIVITY_TYPES.AT_ACTIVITY_DESCRIPTION. - If no matching entry exists for an activity type,
AT_ACTIVITY_DESCRIPTIONstaysNULL.
Dimensions
The "➕ Select Table as Case Dimensions" and "➕ Select Table as Event Dimensions" buttons allow you to reference tables that you can access as additional case and event dimensions respectively. You can change whether the reference is a Table or View before selecting it. The dropdown options are Table or View. Apache Iceberg Tables are supported through the Tables option.
Click the "🗑️" button to remove an existing reference which then allows the selection of different Case or Event Dimensions.
Passthrough Tables
The "➕ Select Table to pass through" buttons allow you to reference tables that are passed through the Snowflake Process Mining App as-is, meaning a view is created for each passthrough table. You can change the type of the passthrough table before selecting a reference. The dropdown options are Table or View. Apache Iceberg Tables are supported through the Tables option.
Click the "🗑️" button to remove an existing reference which then allows the selection of a different Passthrough Table.
Data Filter Page

The Data Filter page allows you to configure filters for the input data. These filters limit which events from the event log are included in the process mining analysis.
Select Time Range
Time Range filters limit which events from the event log are included based on their starting timestamps.
You can choose between the following filter types:
All time (no time filter)- All events from the event log are included in the process mining analysis.Fixed from date until today- Only events with timestamps on or after a specified date are included. Use the From field to specify the starting date.Fixed from date until fixed to date- Only events with timestamps within a specified date range are included. Use the From field to specify the start of the range and the To field to specify the end of the range. The end date must not be earlier than the start date.Rolling window of last X Days/Weeks/Months- Only events from the most recent time period are included. Use the provided input fields to specify the time period as Days, Weeks, or Months and to specify how many such periods should be included. If you choose Weeks, you can also specify which day should be considered as the start of a week.
Rolling windows starting date calculation
When Rolling window of last X Days/Weeks/Months is selected, the given parameters are used to calculate a starting date. Then all events on or after that starting date will be considered. The starting date is calculated to be the start of a period and may change from process mining execution to process mining execution since it is always calculated based on the current execution date. See the following examples to make that more clear.
- Days
- 1 day - All events that occurred any time yesterday (relative to mining execution) or later will be taken into account. So if the mining task runs on June 5, all events from the 4th and 5th will be processed. If the mining task runs on June 6, all events from the 5th and 6th will be processed and so on.
- Weeks - The calculation depends on the configured start of week. The calculated starting date will always be that weekday.
- 1 Week with Monday as start of week - All example dates are in 2025. If the process mining task is executed on October 20, which is a Monday, the calculated starting day will be October 13 (Monday). On October 21 (Tuesday), it will also be the 13th and also on October 26 (Sunday). On October 27, it will switch to October 20.
- 1 Week with Sunday as start of week - All example dates are in 2025. If the process mining task is executed on October 20, which is a Monday, the calculated starting day will be October 12 (Sunday). On October 21 (Tuesday), it will also be the 12th. But on October 26, which is a Sunday, it will switch to the 19th.
- Month
- 1 Month - All events that occurred any time in the last month (relative to mining execution) or later will be taken into account. So if the mining task runs on October 22, the starting date will be September 1. If it runs on October 31, the starting date will also be September 1. If it runs on November 1, the starting date will be October 1 and it will continue to be October 1 throughout November.
Filtering for whole cases
Simply removing all events outside the specified time range from the event log would result in incomplete cases and lead to incorrect variants and measures. For instance, deleting the initial events from certain cases would misidentify subsequent events as start events. To avoid this, the filtering algorithm identifies cases with events occurring within the specified time range. For these cases, all events from the event log are then processed during process mining execution. This reduces the amount of data to be processed to cases with activity during the specified time range, while ensuring consistency in the analyzed cases.
Filter by case start time
When any time range filter other than All time (no time filter) is selected, an additional Filter by case start time checkbox appears.
- Unchecked (default): The behavior is as described under Filtering for whole cases above: cases that have any activity in the configured time range are kept, and all of their events are included in the analysis.
- Checked: Only cases whose first event (case or process start), determined by the chronologically first row for that case in the ordered event log, has a start timestamp that falls within the same time range. All events for those cases are still included in full, so variants and measures stay consistent.
For Rolling window filters, the rolling start date is computed the same way as in Rolling windows starting date calculation; with the checkbox checked, that bound is applied to the first event’s start time instead of to the activity-based selection rule.
Shifts and Holidays Page

The Shifts and Holidays page allows you to configure workdays, holidays and shift times for net time calculations. These configurations are optional and enable precise net time calculations by considering working days, holidays and shift patterns. The configurations use a flexible KEY system that allows you to define different rules for different organizational units, regions or processes within a single analysis.
If you encounter any validation issues while configuring workdays, holidays, or shift times, see Troubleshooting Data Sources Validation for help.
Workdays Configuration
The workdays configuration defines which weekdays are considered working days for different organizational units or processes.
The "➕ Select Table as Workdays" button allows you to reference a table that contains workday definitions. You can change the type of workdays config before selecting a reference. The dropdown options are Table or View. Apache Iceberg Tables are supported through the Tables option.
Click the "🗑️" button to remove an existing reference which then allows the selection of a different Workdays Config table.
For more information on the required table structure, see The Workdays Config.
Holidays Configuration
The holidays configuration defines exception dates (holidays) that should be excluded from net time calculations for different regions or organizational units.
The "➕ Select Table as Holidays" button allows you to reference a table that contains holiday definitions. You can change the type of holidays config before selecting a reference. The dropdown options are Table or View. Apache Iceberg Tables are supported through the Tables option.
Click the "🗑️" button to remove an existing reference which then allows the selection of a different Holidays Config table.
For more information on the required table structure, see The Holidays Config.
Shifts Configuration
The shifts configuration defines working hours within days, allowing you to specify multiple shift patterns for different organizational units or processes.
The "➕ Select Table as Shift Times" button allows you to reference a table that contains shift time definitions. You can change the type of shift times config before selecting a reference. The dropdown options are Table or View. Apache Iceberg Tables are supported through the Tables option.
Click the "🗑️" button to remove an existing reference which then allows the selection of a different Shift Times Config table.
For more information on the required table structure, see The Shift Times Config.
To use these configurations for net time calculations, your event log must contain KEY_WORKDAY, KEY_HOLIDAY and KEY_SHIFT columns that link events to the respective configuration rules. The values in these columns must match the KEY values defined in your configuration tables.
Grouping Page

By defining groups, you can combine related activities to get a better overview of your processes in the process analyzer. Groups can be defined in a hierarchy by configuring one group as the parent of another.
- For more information see Process Analyzer Grouping.
To add a new group, click the "➕" button.
Fill out the Name field with the name of the group.
The Parent Group field lets you define a parent group. Parent groups are optional. A group cannot reference itself as its parent.
Use the Activities field to define which activities belong to your group.
- Click on the "˅" to open a list of activities to choose from.
- Select as many activities as you like, but each activity can only belong to one group.
- Click the "X" next to an activity name to delete it.
To edit an existing group, simply change the field values as required.
To delete an existing group, click the "🗑️" button next to the group.
Subprocess Leadtime Page

Define subprocesses so that lead times and other time-related measures are calculated for partial process segments.
To understand why this is useful, take a look at the Subprocess Leadtime » Use Cases.
Add a New Subprocess
To add a new subprocess, click the "➕" button and fill out the fields appropriately.
The Subprocess field lets you define a name for your subprocess.
Use the Start Activity field to select all activities that mark the start of the subprocess.
The Include Start Activity check mark below defines whether the duration of the activity will be included in or excluded from the calculated lead time.
Sometimes you may have more than one activity marked as the Start Activity show up in a process variant - either because two different start activities appear or a single start activity is repeated. The Min/Max Start Activity field is then used to define if the first or last matching activity will be used for lead time calculation. Min uses the first matching activity (resulting in a longer process leadtime), while Max uses the last matching activity (resulting in a shorter process leadtime).
Use the End Activity field to select all activities that mark the end of the subprocess.
The Include End Activity check mark below defines whether the duration of the activity will be included in or excluded from the calculated lead time.
By configuring the Min/Max End Activity field for the End Activity you can define if the first or last matching activity will be used for lead time calculation. Here the resulting impact is opposite of that for the Start Activity. Min uses the first matching activity (resulting in a shorter subprocess leadtime), Max uses the last matching activity (resulting in a longer subprocess leadtime).
The Target Time [d] and Target Time Operator fields define the desired lead time for the subprocess. They are used to calculate whether the lead time has been missed.
End of Process Page

By default, the mpmX app shows leadtimes and other information from an average of all cases, but this can sometimes be misleading.
- For example, cases that are not finished will have shorter leadtimes just because they have not reached the end.
- The number of process variants (specific path that each case takes) will be greater if you include both open and closed cases, than if you only counted closed cases.
On the End of Process page you can define when a process is considered to be completed.
- If the End of process condition is set to None, all processes are considered to be completed.
- Select using Activity to then select an activity which marks a process as completed.
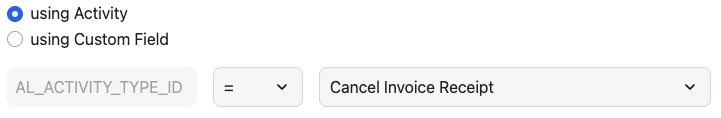
End of Process - using Activity - Select using Custom Field to define more complex conditions.
- On the left, you can define which field of the activity log should be used.
- In the middle select the appropriate operator (= or IN).
- On the right, define the value (in case of =) or the comma-separated list of values which mark a process as completed.

End of Process - using Custom Field
Time Travel Page
Time Travel allows you to keep advanced historical information to enable a more detailed analysis of changes over time.
Time Travel is only available for Snowflake Enterprise Edition accounts (and higher).
The Data Retention Time [d] field allows you to configure for how many days historical information should be retained. The maximum value is 90 days.
Please note, that this will result in additional storage costs.
Additional Parameters Page
On the Additional Parameters page you can configure some rework and automation settings as well as some miscellaneous settings.

Rework
A rework event is any activity that indicates an unexpected change, such as a Purchase Order being adjusted or deleted.
By selecting a Rework definition option you can define which kinds of events should be taken into account when calculating rework related measures. Options are
<empty>- rework related measures will not be calculatedReworkEvent- events are considered if they are defined as rework (see Rework Event Expression (by activity type) below)RepeatedEvent- events are considered if they are repeated in a loopReworkAndRepeatedEvent- events are considered if they are defined as rework AND are repeatedReworkOrRepeatedEvent- events are considered if they are defined as rework OR are repeated
An event is regarded as rework if its activity type matches the Rework Event Expression (by activity type).
Automation
- The Automation limit [%] indicates the percentage of automated events that a case needs to have to be labeled as an automated case.
- An event is regarded as automated if its user name field matches the Automated Event Expression (by user name).
Resource Analysis
Resource Analysis is an optional feature which lets you use the Resource Analysis sheet.
- If No resource analysis is selected, no resource analysis will be performed during the process mining execution.
- Selecting Analyse users as resource will result in a resource analysis being performed with regard to the users who executed an event. This option only appears if the event log contains a column called
EL_USERNAME. For more information on the input event log, see Snowflake input data. - Selecting the option Analyse general resource placeholder as resource will result in a resource analysis being performed based on the values given in the
EL_RESOURCEcolumn. This option only appears if the column is present in the event log. For more information on the input event log, see Snowflake input data.
Miscellaneous
- If Reduce timestamps? is checked, the number of distinct timestamps is reduced by flooring seconds and milliseconds to minutes. The lead and process times are not influenced, just the final timestamp output format is shortened to minutes.
- If Fold loops for activity repetitions is checked, process variants that differ only in the number of times a loop is executed are merged into a single looped variant. For example, A → B → B → D, A → B → B → B → D and A → B → B → B → B → D are treated as the same variant. All repetitions are kept in the event log but there will be fewer distinct variants.
- Check Run pareto analysis to enable Pareto/ABC Analysis.
Conformance Checking Page
Conformance Checking is an optional module in mpmX and will unlock the analysis in the Conformance sheet.
On the Conformance Checking page you can define your Happy Paths, or ideal process paths, as well as configure other mining related settings.

Conformance Checking Parameters
- Use the Only finished cases? field to control whether only finished cases should be regarded or not.
- The Optimization Potential Threshold defines which cases will be analyzed for process governance optimization potential by comparing the happy path fitness of the case to the specified threshold:
- By default, the threshold is set to 0.8 (80%).
- To customize the threshold, check the Adapt threshold checkbox, then enter a value between 0.0 and 1.0 in the Optimization Potential Threshold field. The value can be adjusted in increments of 0.01.
Happy Path Groups
Happy path groups allow you to organize related happy paths. Groups help structure your conformance checking configuration when you have many ideal process paths.
To add a new group, click the "➕" button next to the Happy Path Groups section.
- Use the Name field to assign your group a meaningful name. Group names must be unique.
- To delete an existing group, click the "🗑️" button next to the group. When deleting a group that contains happy paths, you can choose whether to also delete those happy paths or to unassign them from the group.
Happy Paths
This is where you define your happy paths.
To add a new happy path, click the "➕" button and fill out the fields appropriately.
- Use the Name field to assign your happy path a meaningful name.
- Use the Group field to assign the happy path to a group. This is optional; happy paths can also exist without a group.
- Use the Description field to describe what the happy path represents.
- The Process Path defines the ideal sequence of activities. Build it interactively:
- In the left column, browse the list of available activities. You can search and filter activities by type or object types.
- Click the arrow button (→) next to an activity to add it to your happy path sequence.
- In the right column, view your selected activity sequence. You can reorder activities using the up/down arrow buttons, or remove activities using the delete button.
- The Condition field (optional) allows you to limit which cases the happy path is checked against:
- Enable the condition by checking the Condition checkbox.
- Enter a JSON Logic expression in the text area that appears. This expression defines which cases should be evaluated against this happy path.
- If Active is checked, then this happy path will be used in the process mining.
To edit an existing happy path, simply change the field values as required.
To delete an existing happy path, click the "🗑️" button next to the happy path.
You can also import happy paths from a BPMN diagram; see Import Happy Paths from BPMN below.
Import Happy Paths from BPMN
The Import Happy Paths from BPMN page allows you to create happy paths and groups from a BPMN process diagram. This is useful when you have an existing process model and want to use it as the basis for conformance checking.
Access the import page via the link in the Happy Paths section on the Conformance Checking page. The import page is only available when the scenario has been initialized (data sources configured).
Input
- Provide the BPMN XML by pasting it into the text area.
- Enter a Group name for the imported happy paths. This name must be unique among existing groups. The imported paths will be created under this new group.
Parse
- Click the Parse button to extract process paths from the BPMN diagram. The parser usually uses the first process in the BPMN file. However, if your BPMN diagram is a collaboration diagram involving multiple participants, all of the participant processes are treated as one combined process for the purposes of path extraction.
- After a successful parse, the extracted BPMN activities are listed for mapping.
Mapping
- Map each BPMN activity to a corresponding activity type from your event log. Use the dropdown next to each BPMN activity to select the process-mined activity type.
- BPMN activities that are not mapped are skipped when building the process path. Consecutive steps that map to the same event log activity are merged into a single step.
- Duplicate paths (after mapping) are not imported.
Import
- Click the Import paths button to create the new group and happy paths. After a successful import, you are redirected back to the Conformance Checking page.
Impact Analysis Page
The Impact Analysis helps users identify key drivers behind performance deviations in business processes. It is the modern replacement for the legacy Root Cause Analysis sheet, using a simplified data model that is easier to set up and maintain.
In the Snowflake Process Mining app this follows Core mode, the same conceptual model as Use Root Cause Analysis (RCA) on Your Data for Qlik (that page describes both legacy extended RCA and Core mode). When Impact Analysis is enabled and at least one dimension is selected, each mining run materializes ROOT_CAUSE_DIMENSION and CASE_ROOT_CAUSE_LINK in your scenario output schema. See Impact Analysis tables (Core mode) for column definitions.
The scenario wizard includes Impact Analysis after Conformance Checking. There you can:
- Enable Impact Analysis and choose Dimensions for Impact Analysis from your configured case dimensions (fields prefixed with
CD_in the mined model). You must add a Case Dimensions reference on Data Sources first; otherwise no dimensions are available. - Leave Impact Analysis disabled if you do not need these tables.
Configuration is saved automatically. Extended (legacy) Root Cause Analysis with backend statistical probability tables is not available in the Snowflake app—only Core mode star-schema output.
Scenario export and import include Impact Analysis settings as a top-level rca object (enabled, columns); see Process scenario configuration (JSON Schema v1).
Task Execution Page

Task Execution Warehouse
The "Overwrite default warehouse" button allows you to specify a warehouse that is used solely by the process mining tasks. You can specify a different warehouse for each scenario, enabling you to select the most suitable warehouse size for your dataset.
Clicking the "Use default warehouse" button resets the warehouse reference so that the default warehouse is used by the process mining tasks once again.
The "Change warehouse" button allows you to update the referenced warehouse alongside with your evolving dataset.
Task Execution Scheduling
- This section allows you to configure a schedule for regular automatic process mining runs by defining a Cron expression and a time zone. To understand how a cron expression is structured, please refer to the Snowflake documentation: Snowflake » Schedule using cron »
SCHEDULE ...»USING CRON <expr> <time_zone>
Ad-hoc Task Execution
- The Start Mining Task button allows you to manually start a process mining task.
Mining Summary of last execution
- This section shows the basic KPIs of the process model after a successful mining run.
Task Execution History
The Task Execution History section displays the status of the most recent process mining runs.
- The Start (UTC) and End (UTC) columns contain the start and end timestamps of the mining run
- Duration (hh:mm:ss) contains the total time of the mining run.
- The States column contains one of the following values:
- Running - The process mining task is running.
- Failed - The process mining task has failed. Error details can be found in the Error Message column.
- Succeeded - The process mining task was successful.
- Scheduled - The process mining task is scheduled to run at the displayed Start (UTC) time.
- An Error Message will appear if anything went wrong.
App Settings Page
This page allows you to configure the application's operational parameters for background processing. The page is divided into two main sections.

Task Execution
This indicates whether or not the app has the EXECUTE TASK privilege.
Default Warehouse
The "Change default warehouse" button allows you to change the referenced warehouse used to run small background tasks.
It is also used as a fallback for the process mining task. We recommend that you select a warehouse of size XSMALL and overwrite the process mining warehouse per scenario with a warehouse of an appropriate size for your dataset.
If the app shows 1 hidden warehouse here, the warehouse reference is broken; see Troubleshooting: Broken warehouse reference to fix it.
See also: Installation and Update » Warehouses
Backup and Restore Page
The Backup and Restore page helps you safeguard your process mining scenarios and recover them when needed. This page is divided into two main sections: Backup Location and Restore Backup.

Backup Location
Before creating backups, you must define a backup location — a dedicated table in your Snowflake account:
USE SCHEMA <DATABASE>.<SCHEMA>;

CREATE TABLE MPMX_SCENARIOS (
    SCENARIO_NAME VARCHAR(16777216),
    SCENARIO_CONFIG VARCHAR(16777216),
    CREATED_AT TIMESTAMP_NTZ(9)
);
How to set the backup location:
- Click the "Select Backup Location" button.
- A dialog will appear requesting permission to access a table. The app requires the following privileges:
DELETE,INSERT,SELECT, andUPDATE. - Click "+ Select Data" to choose a table in your account.
- Click "Save" to confirm your selection.
- The chosen backup location will now be displayed in the interface.

Restore Backup
You can restore scenarios from the backup location as long as no scenarios currently exist in the app. Ensure a backup location is configured first.
The restore process follows a three-step wizard:
- Step 1: Select scenarios to restore.
- Step 2: Load and reconnect data sources.
- Step 3: Review the summary and confirm the restore.
Step 1: Select scenarios
Browse the list of available scenario backups and select the ones you want to restore using the checkboxes. You can also use "Select All" or "Clear All".

If a scenario cannot be restored, a warning message will appear:

Deselect any invalid scenarios before continuing.
Click "Continue" to proceed.
Step 2: Load data sources
To reconnect data sources:
Unfortunately, due to Native App restrictions it is not possible to connect the data sources to the imported scenarios automatically, but the wizard will support you in doing so manually.
- The app provides SQL scripts for each scenario.
- Each script registers a table or view as a data source.
- Copy the SQL code into a Snowflake SQL Worksheet and execute it.
Click "Abort Restore" to cancel the restore process and delete any partially restored scenarios.
Click "Continue" to proceed.

Step 3: Summary
The summary displays:
- Total scenarios found in the backup location.
- Number of scenarios successfully loaded.
- Any scenarios missing data source connections (these scenarios will still be restored, but require manual reconnection in edit mode).
Click "Abort Restore" to cancel the restore process and delete any partially restored scenarios.
Click "Complete Restore" to finalize the process.
